

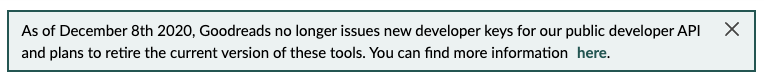
Since Goodreads no longer supports fetching user’s books data via their API, I’ve decided to crawl / scrape user’s book data. There are two primary ways to do this: using the RSS feed or by exporting your library as a CSV file.
No matter which method you choose, we’ll parse everything into a clean, consistent format. Here’s what our final GoodreadsBook type looks like:
export type GoodreadsBook = {
guid: string
pubDate: string
title: string
link: string
id: string
bookImageUrl: string
bookSmallImageUrl: string
bookMediumImageUrl: string
bookLargeImageUrl: string
bookDescription: string
authorName: string
isbn: string
userName: string
userRating: string
userReadAt: string
userDateAdded: string
userDateCreated: string
userShelves: string
userReview: string
averageRating: string
bookPublished: string
content: string
}
The first method is to use the rss-parser package to parse the RSS feed and extract the book data.
import Parser from 'rss-parser'
import type { GoodreadsBook } from '~/types'
let parser = new Parser<{[key: string]: any}, GoodreadsBook>({
customFields: {
// Define all the custom fields you want to extract from the RSS feed
// Here I'm listing all the available fields from the Goodreads RSS feed
item: [
'guid',
'title',
'link',
'pubDate',
['book_id', 'id'],
['book_image_url', 'bookImageUrl'],
['book_small_image_url', 'bookSmallImageUrl'],
['book_medium_image_url', 'bookMediumImageUrl'],
['book_large_image_url', 'bookLargeImageUrl'],
['book_description', 'bookDescription'],
['author_name', 'authorName'],
['isbn', 'isbn'],
['user_name', 'userName'],
['user_rating', 'userRating'],
['user_read_at', 'userReadAt'],
['user_date_added', 'userDateAdded'],
['user_date_created', 'userDateCreated'],
['user_shelves', 'userShelves'],
['user_review', 'userReview'],
['average_rating', 'averageRating'],
['book_published', 'bookPublished'],
],
},
})
Then you can fetch the data from the RSS feed using the parser object, and process it as needed.
const GOODREADS_RSS_FEED_URL = '<YOUR_GOODREADS_RSS_FEED_URL>'
export async function fetchGoodreadsBooks() {
if (GOODREADS_RSS_FEED_URL) {
try {
let data = await parser.parseURL(GOODREADS_RSS_FEED_URL)
// All the books data will be stored in the `data.items` array
// Use the parsed data as needed, for example, you can write it to a JSON file:
writeFileSync(`./json/books.json`, JSON.stringify(data.items))
} catch (error) {
console.error(`Error fetching the Goodreads RSS feed: ${error.message}`)
}
} else {
console.log('📚 No Goodreads RSS feed found.')
}
}
[!NOTE] You can get a Goodreads user’s RSS feed URL by going to their profile and navigating to the bookshelf page and copy the RSS feed URL. This is my bookshelf page for example: https://www.goodreads.com/review/list/179720035
Now that you have the data you might need to prettify them before storing or using in your application since the data is stored in a raw format.
let data = await parser.parseURL(/* GOODREADS_RSS_FEED_URL */)
// Loop through the `data.items` array to prettify the data
for (let book of data.items) {
book.content = book.content.replace(/\n/g, '').replace(/\s\s+/g, ' ') // Remove line breaks
book.book_description = book.book_description
.replace(/<[^>]*(>|$)/g, '') // Remove HTML tags
.replace(/\s\s+/g, ' ') // Replace multiple spaces with a single space
.replace(/^[\"|“]|[\"|“]$/g, '') // Remove leading and trailing quotation marks
.replace(/\.([a-zA-Z0-9])/g, '. $1') // Add a space after a period
}
// Use the parsed and prettified data as needed...
Using a CSV Export
The second method involves exporting your Goodreads library as a CSV file and parsing it. This method gives you more data fields than the RSS feed.
First, you need to export your data from the Goodreads import/export page.
Once you have the goodreads_library_export.csv file, you can use the csv-parser package to parse it.
import fs from 'node:fs'
import path from 'node:path'
import csv from 'csv-parser'
import type { GoodreadsCsvBook } from '~/types'
const GOODREADS_CSV_FILE_PATH = path.join(
process.cwd(),
'your/path/to',
'goodreads_library_export.csv',
)
export async function parseGoodreadsCsv() {
if (!fs.existsSync(GOODREADS_CSV_FILE_PATH)) {
console.log('📚 Goodreads CSV file not found.')
return
}
let csvBooks: GoodreadsCsvBook[] = []
await new Promise<void>((resolve, reject) => {
fs.createReadStream(GOODREADS_CSV_FILE_PATH)
.pipe(
csv({
mapHeaders: ({ header }) => {
// Map CSV headers to a more usable format
let headerMap: Record<string, string> = {
'Book Id': 'id',
'Title': 'title',
'Author': 'authorName',
'ISBN': 'isbn',
'My Rating': 'userRating',
'Average Rating': 'averageRating',
'Publisher': 'publisher',
'Number of Pages': 'numberOfPages',
'Year Published': 'bookPublished',
'Original Publication Year': 'bookPublished',
'Date Read': 'userReadAt',
'Date Added': 'userDateAdded',
'Bookshelves': 'userShelves',
'Exclusive Shelf': 'exclusiveShelves',
'My Review': 'userReview',
'Binding': 'binding',
}
return headerMap[header] || header.toLowerCase().replace(/\s+/g, '')
},
}),
)
.on('data', (book: GoodreadsCsvBook) => {
csvBooks.push(book)
})
.on('error', reject)
.on('end', resolve)
})
// Now csvBooks contains all the data from the CSV
// You can then transform it to your desired format
console.log(`Found ${csvBooks.length} books in the CSV.`)
}
The data from the CSV needs to be transformed to a consistent format, similar to the one used for the RSS feed data. Notice that some fields like bookImageUrl are not available in the CSV export.
// Transform CSV data to match a common GoodreadsBook format
let books: GoodreadsBook[] = csvBooks.map(book => {
let transformedBook: GoodreadsBook = {
id: book.id || '',
guid: `goodreads-${book.id}` || '',
pubDate: book.userDateAdded || new Date().toISOString(),
title: book.title || '',
link: `https://www.goodreads.com/book/show/${book.id}`,
bookDescription: book.userReview || book.title || '',
authorName: book.authorName || '',
isbn: book.isbn?.replace(/[=""]/g, '') || '',
userRating: book.userRating || '0',
userReadAt: book.userReadAt || '',
userDateAdded: book.userDateAdded || new Date().toISOString(),
userDateCreated: book.userDateAdded || new Date().toISOString(),
userShelves: book.userShelves || book.exclusiveShelves || '',
userReview: book.userReview || '',
averageRating: book.averageRating || '0',
bookPublished: book.bookPublished || book.yearPublished || '',
content: book.userReview || book.title || '',
}
// ... any further processing like cleaning up descriptions
return transformedBook
})
// Use the transformed data as needed, for example, write it to a JSON file or store in a database
- Pros: Can be automated to fetch data periodically.
- Cons: Data refresh is not instant (can take hours). Provides fewer data fields compared to the CSV export.
CSV Export
- Pros: Contains more detailed information about the books (e.g., publisher, number of pages, binding). The data is available immediately after export.
- Cons: No image fields. You’ll need to fetch book covers separately. Exporting CSV is manual.
Choose your preferred method and happy crawling! 